NIME_2026_examples
This webpage features audio and visual examples for the following publication:
Strauss, L., Thattai Ravikumar, P., Yee-King, M. ‘Cross-Modal Sig2Sig Machine Translation with Deep Generative Modeling for NIME Design’. International Conference on New Interfaces for Musical Expression, 2026.
GitHub: MLMLMLM GitHub Repository
Music: Artistic Research Project Page
This Page: Listening Examples
LISTEN
EA Experiments
Below is a tabulation of model outputs from the interim training phase, corresponding to Tables 3 & 4, Section 6.1 in the associated publication. Each playback features four pairs of original and reconstructed signals. Original and reconstructed samples are interleaved.
BEWARE OF SUDDEN LOUD CLICKS!!! LISTEN TO EACH SAMPLE WITH LOW VOLUME FIRST!!!
| EA VAE 1 | epoch 113 | |
| EA VAE 2 | epoch 96 | |
| EA VAE 3 | epoch 96 | |
| EA VAE 3 | epoch 113 | |
| EA VAE 4 | epoch 113 |
MLMLMLM Outputs
The following listening examples are model outputs using the full MLMLMLM architecture, composed of two RVQ-VAEs and a Transformer decoder in latent space. In TE1, the cross-attention causal mask and kv caching were not yet implemented. TE2 outputs are truly causal and autoregressive with streaming conditioning, as described in Section 7 of the associated publication.
| TE1 | epoch 100 | |
| TE1 | epoch 99 | |
| TE1 | epoch 98 | |
| TE1 | epoch 97 |
| TE2 | epoch 100 | |
| TE2 | epoch 99 | |
| TE2 | epoch 98 | |
| TE2 | epoch 97 |
LOOK
EA VAE 3 outputs
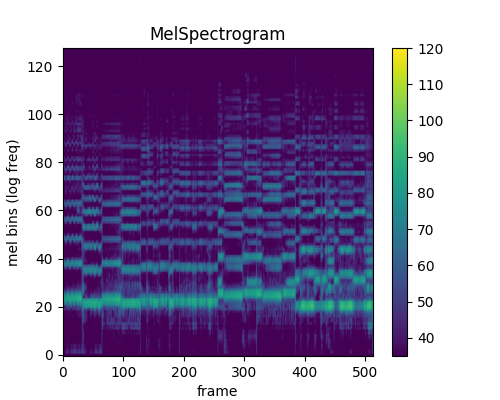
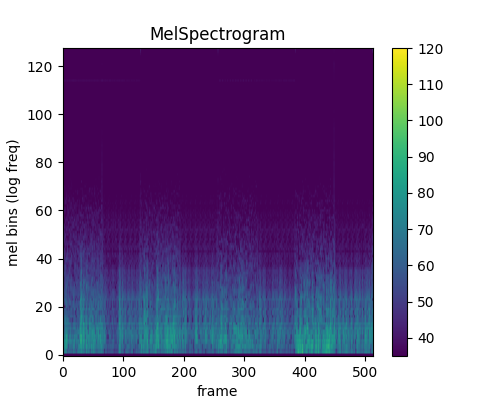
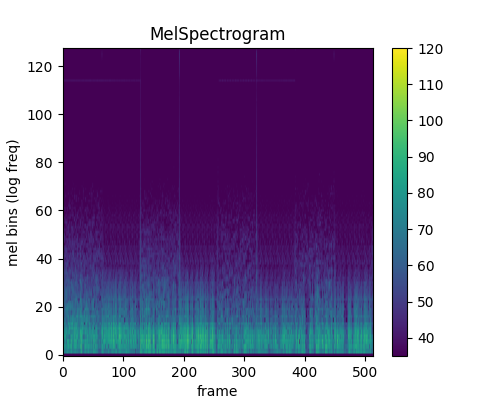
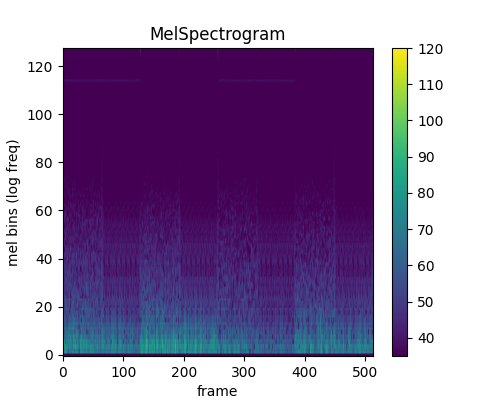
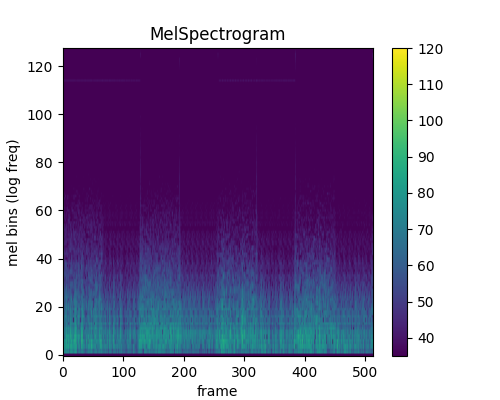
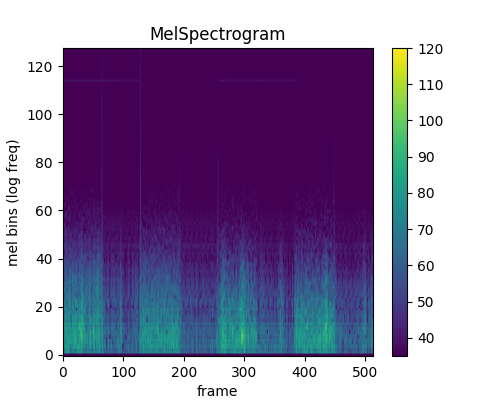
Below are some spectrogram representations of original and reconstructed signal samples from experiment EA VAE 3 during training. The paper reports loss values at 113 epochs for ease of comparison with other runs. However, during training, we noticed that this run was looking promising and continued training for a total of 175 epochs. These spectrograms are from the end of training. Notice that they are even clearer than those presented in Appendix B of the associated publication. Especially notice the improved accuracy of the reconstructions for channel 6.